I'm an undergrad at Stanford studying computer science and philosophy. I work on memory and continual learning for generalist robot policies at the Stanford AI Lab, where I'm part of the IRIS group advised by Chelsea Finn. I previously spent a summer at Google working on Gemini Enterprise for CX.
research
- Combining Symbolic and Perceptual Memory for Long-Horizon Robot Manipulation
Aaditya ShahRobots doing long tasks need memory, but language subgoals and raw visual history each win on different tasks. We train one π0.5 policy that uses both, reaching 52.3% success on the 16-task RoboMME benchmark versus 45.7% and 46.8% for either alone. A fine-tuned VLM writes subgoals into the policy's language prompt, while a bank of sampled past frames steers its action expert directly.
CS231N: Deep Learning for Computer VisionNominated for Best Paper Award - RECAP-Ψ: Advantage-Conditioned Fine-Tuning for Open-Source Humanoid VLAs
Jonathan Lu*, Aaditya Shah*, Karthik Pythireddi*Humanoid VLAs learn by imitation, so they can't tell their good attempts from their bad ones. We ran the first reproduction of Physical Intelligence's RECAP on an open-source model, Ψ0, using just 500 simulated rollouts. Advantage conditioning beat plain behavior cloning on the same data (30.8% vs. 18.2% success) on a whole-body bend-and-pick task.
CS224R: Deep Reinforcement Learning 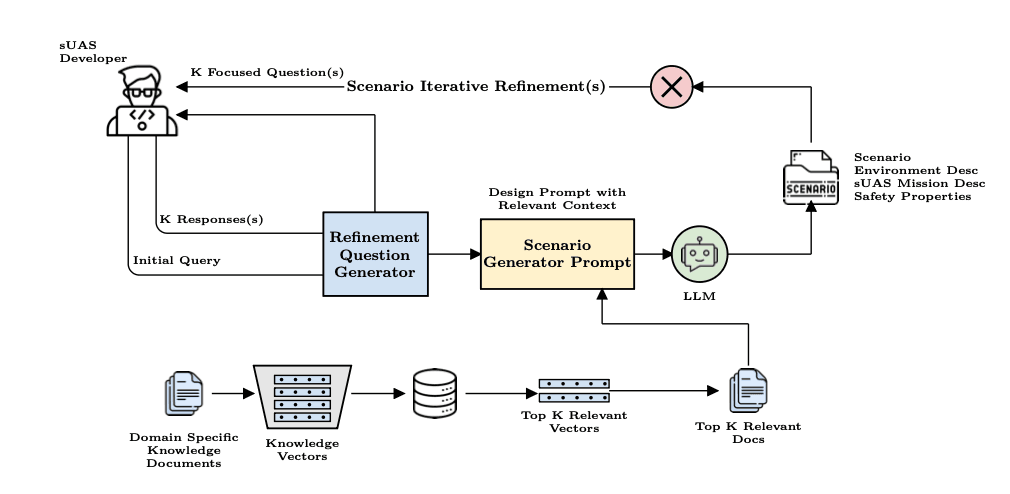 Agentic LLM-Driven Simulation Testing and Automated Analysis for Small Uncrewed Aerial Systems
Jithin Garapati, Aaditya Shah, Bohan Zhang, Michael Vierhauser, Ankit AgrawalTesting small drones in simulation is still mostly manual, which limits how many scenarios developers can cover. We propose AutoSimTest, where LLM agents collaborate to write test scenarios, configure the simulator, generate missions and analyze the flight logs. On 10 real PX4 incidents, its diagnoses scored 9.5/10, closely matching those of experienced PX4 developers.
Preprint
projects
- Teaching a pixel robot to stack crates
How to use reinforcement learning to teach an old robot new tricks. - Predator–Prey Simulator
A C++ simulation where predator and prey agents are driven by neural networks evolved over generations, so hunting and evasion emerge from selection alone. - krates
Your AI devops engineer before you can afford to hire one — automating Docker and Kubernetes for early-stage teams.CalHacks 12.01st place, YC Track
Last updated: October 2026
aadi2 [at] stanford [dot] edu